Moving a generative artificial intelligence application from a proof-of-concept to a large-scale production environment exposes a major issue. Infrastructure expenditure scales rapidly. As user adoption accelerates, the massive volume of API calls to foundational language models can quickly erode profit margins. For product teams and enterprise architects, rigorous LLM API cost optimization is a fundamental requirement for building a scalable business model.
TL;DR: Unified AI billing and cost management
Comprehensive LLM API cost optimization requires dynamic model routing and context caching. Moving away from fragmented vendor subscriptions also plays a key role. Consolidating infrastructure through a unified AI billing platform like ScriptRun simplifies accounting, unlocks wholesale pricing, and provides robust financial controls via a single B2B-ready endpoint.
AI token pricing: Understanding the economics
Figuring out how to reduce AI API bills requires engineering teams to dissect the underlying billing mechanics of AI providers. Foundational models bill based on token volume rather than computing hours. As a general heuristic, one token corresponds to approximately 0.75 English words, though different tokenizers can interpret the exact same string of text differently, creating hidden price variances across providers.
AI token pricing heavily depends on the dichotomy between input and output tokens. Input tokens encompass the system prompt, contextual documents, and the user query. Output tokens represent the novel text generated by the model. Because text generation demands intense GPU resources, output tokens are consistently priced higher than input tokens.
Applications built around document summarization or code generation face massive output costs. Systems designed to classify user intent based on extensive knowledge bases suffer from inflated input costs. Teams aiming to reduce OpenAI costs must monitor these ratios closely.
Calculating token costs for LLM apps
Predictive financial modeling requires precision. AI developers traditionally split input and output costs. Enterprise API platforms like ScriptRun simplify this math. The API returns an external_cost_usd object immediately after every execution. It clearly separates the raw AI execution cost from the marketplace commission. For predictive budget planning, the calculation remains linear:
Total Cost = (Total Tokens / 1,000,000) × Unified Model Rate
Consider an enterprise customer support platform generating one million interactions monthly. An average interaction requires 2,400 total tokens. Routing every request through a premium model like GPT-4o (at an enterprise rate of $20.00 per 1M tokens) yields a baseline infrastructure cost of $48,000 per month. Shifting those exact identical workloads to GPT-4o mini (priced at $1.20 per 1M tokens) drops the cost to $2,880 immediately. Smart LLM API cost optimization protects your budget without degrading the end user experience.
Architecting for efficiency: AI API cost management
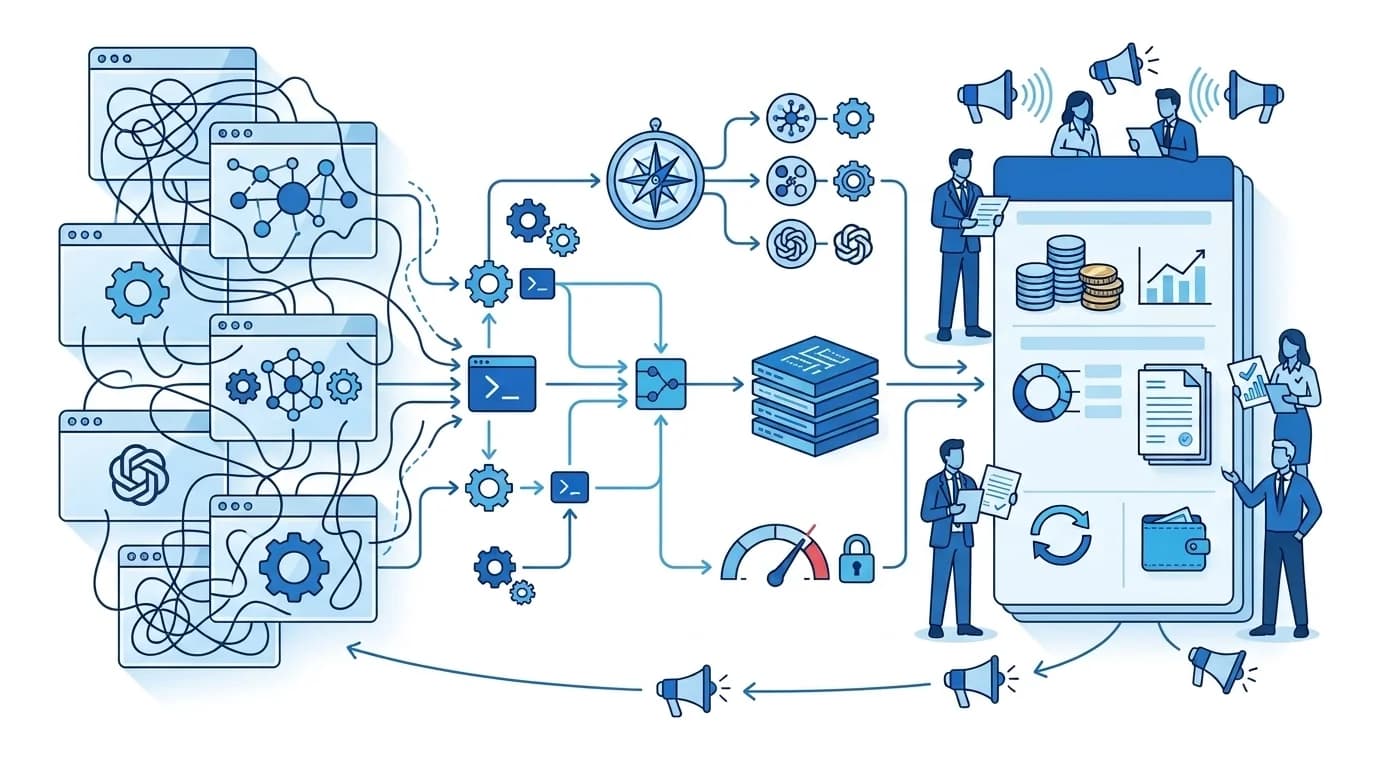
Cutting cloud computing bills requires a shift in application architecture. Here are three practical methods to reduce OpenAI costs. They optimize your infrastructure without degrading the quality of generated responses.
1. Smart routing to cheaper LLM alternatives
A common source of budget exhaustion is the misallocation of compute resources. Developers frequently default to utilizing apex models for trivial operations. Complex mathematical reasoning or nuanced code refactoring necessitates models like Claude Sonnet 4.5. Standard tasks such as entity extraction, JSON formatting, or semantic routing do not.
Implementing an intelligent API gateway enables dynamic model routing based on task complexity. The market offers highly optimized compact models that deliver excellent performance for structured tasks.
When you compare GPT and Claude pricing against optimized compact models within a unified B2B gateway, the opportunity for arbitrage becomes evident:
Model
Unified Pricing (per 1M)
Optimal Workload
Gemini 2.5 Flash-Lite
$0.80
High-throughput data parsing
GPT-4o mini
$1.20
Standard agentic tasks
Gemini 2.5 Flash
$5.00
Multimodal long-context workflows
GPT-4o
$20.00
Frontier reasoning
Claude Sonnet 4.5
$30.00
Advanced logic and coding
Directing 80% of routine background operations to models like Gemini 2.5 Flash-Lite or GPT-4o mini represents profound AI API cost management. Enterprise gateways facilitate this transition. They allow applications to switch models seamlessly without modifying existing SDK setups.
LLM context caching has radically altered the economics of high-context applications. In Retrieval-Augmented Generation (RAG) setups, applications iteratively send massive, identical system prompts and corporate documents with every single user interaction.
Leading providers now support prefix caching mechanisms. When an application transmits a large block of text, the provider retains it in memory. Subsequent requests utilizing the exact same prefix trigger a cache read, which is billed at an extraordinary discount. Empirical benchmarks demonstrate that Anthropic and Google Gemini discount cached inputs by up to 90% compared to a standard cache miss.
By structuring prompts to place static knowledge bases at the absolute beginning of the context window, developers maximize cache hits. This technical layer of LLM API cost optimization effectively neutralizes the financial penalty of large context lengths.
3. Visual workflows over raw API calls
The cheapest AI call is the one never made. Utilizing the ScriptRun visual workflow builders allows technical teams to embed deterministic logic directly into the execution path. True LLM API cost optimization relies heavily on standard webhooks.
By integrating conditional branching (if/else nodes), the system evaluates a query before it triggers an LLM. If a user asks for a standard database lookup, the workflow resolves it instantly via dedicated HTTP nodes. This bypasses the language model entirely. Token balances stay intact, and application latency drops significantly.
Engineering optimizations fail to resolve the administrative burden placed on corporate finance departments. Procuring AI capabilities globally often requires juggling multiple corporate credit cards, reconciling fragmented invoices, and managing service interruptions due to compliance issues.
Adopting a gateway that provides unified invoicing for AI models solves these administrative blocks. Transitioning to the ScriptRun B2B unified AI billing platform fundamentally streamlines operations:
Consolidated financial operations: Organizations fund a centralized project balance using localized corporate methods, including standard bank wire transfers, credit cards, and crypto payments.
Enterprise B2B billing: Legally compliant invoices, contracts, and closing documents are generated automatically. This eliminates the accounting friction associated with purchasing SaaS from disjointed providers.
Single API compatibility: Developers manage access through a single key. The /v1/chat/completions endpoint acts as a synchronous drop-in replacement for the OpenAI SDK. Migrating existing chats requires only updating the base_url and passing the key via an Authorization: Bearer header. Complex automations run through the dedicated Workflow API using an X-Api-Key header.
Absolute budget control: The platform features auto top-up and strict budget limits per project. The dedicated /billing-history/ endpoint pulls a complete transaction breakdown for every execution (WorkflowRun) down to the specific node. It tracks total spending in both USD and platform SR currencies. This grants total observability over token consumption.
Merging sophisticated traffic routing with robust financial administration builds a secure foundation for highly profitable AI applications. This centralized approach guarantees sustainable LLM API cost optimization across all enterprise departments.
Crea automatizaciones, conecta APIs y accede a más de 50 modelos de IA desde una sola plataforma.
Constructor visual de workflows
API compatible con OpenAI
Mercado de workflows y plantillas
Empieza gratis, planes desde $5
FAQs about LLM API cost optimization
What does comprehensive LLM API cost optimization entail?
LLM API cost optimization is a holistic strategy combining technical and financial adjustments. It involves implementing smart routing to direct simple queries to cheaper LLMs, structuring prompts to maximize LLM context caching, and using centralized API gateways to consolidate infrastructure spending.
How is calculating token costs for LLM apps typically performed?
Calculating token costs requires tracking input and output data. Enterprise API platforms simplify this by offering a unified rate for total tokens consumed. You multiply your total token usage by the assigned model rate.
Can unified invoicing for AI models solve corporate accounting issues?
Absolutely. Unified AI billing platforms, such as ScriptRun, act as a master vendor. Instead of managing multiple credit cards across various AI labs, businesses fund a single account using B2B-friendly methods like wire transfers or crypto payments, receiving one set of consolidated invoices.
What are the most reliable cheaper LLM alternatives to frontier models?
Models such as Gemini 2.5 Flash-Lite and GPT-4o mini currently lead the market for standard business workflows. They are exceptionally capable at classification and intent recognition at a fraction of the price of heavy models.
Why is understanding AI token pricing critical for RAG applications?
RAG (Retrieval-Augmented Generation) applications rely heavily on input tokens because they repeatedly send large documents to the model. Understanding that input tokens can be heavily discounted through LLM context caching allows developers to drastically reduce recurring costs.
How exactly does LLM context caching reduce OpenAI costs?
When a large block of text is sent to the API, it is stored in the provider's cache. If a subsequent request begins with that exact identical text, the provider reads from the cache rather than reprocessing the entire prompt. This cache read operation is billed at a significantly discounted rate, sometimes up to 90% cheaper.
Does utilizing a unified API gateway impact system reliability?
It improves it. Leading gateways incorporate automatic failover routing. If the primary model provider experiences an outage, the gateway can seamlessly reroute the traffic to an equivalent model from a different provider.
Learn how to measure API latency, benchmark DeepL requests, investigate Discord delays, and improve AI API performance. Set realistic targets and test changes without overlooking reliability, output quality, or cost.
Is ChatGPT General Purpose Technology? Explore the evidence, what it means for businesses, and how ScriptRun helps turn AI capabilities into repeatable processes.
Compare 8 AI coding assistants by job, not hype: current 2026 pricing, agent features, privacy options and the limits vendors leave out of their pages.